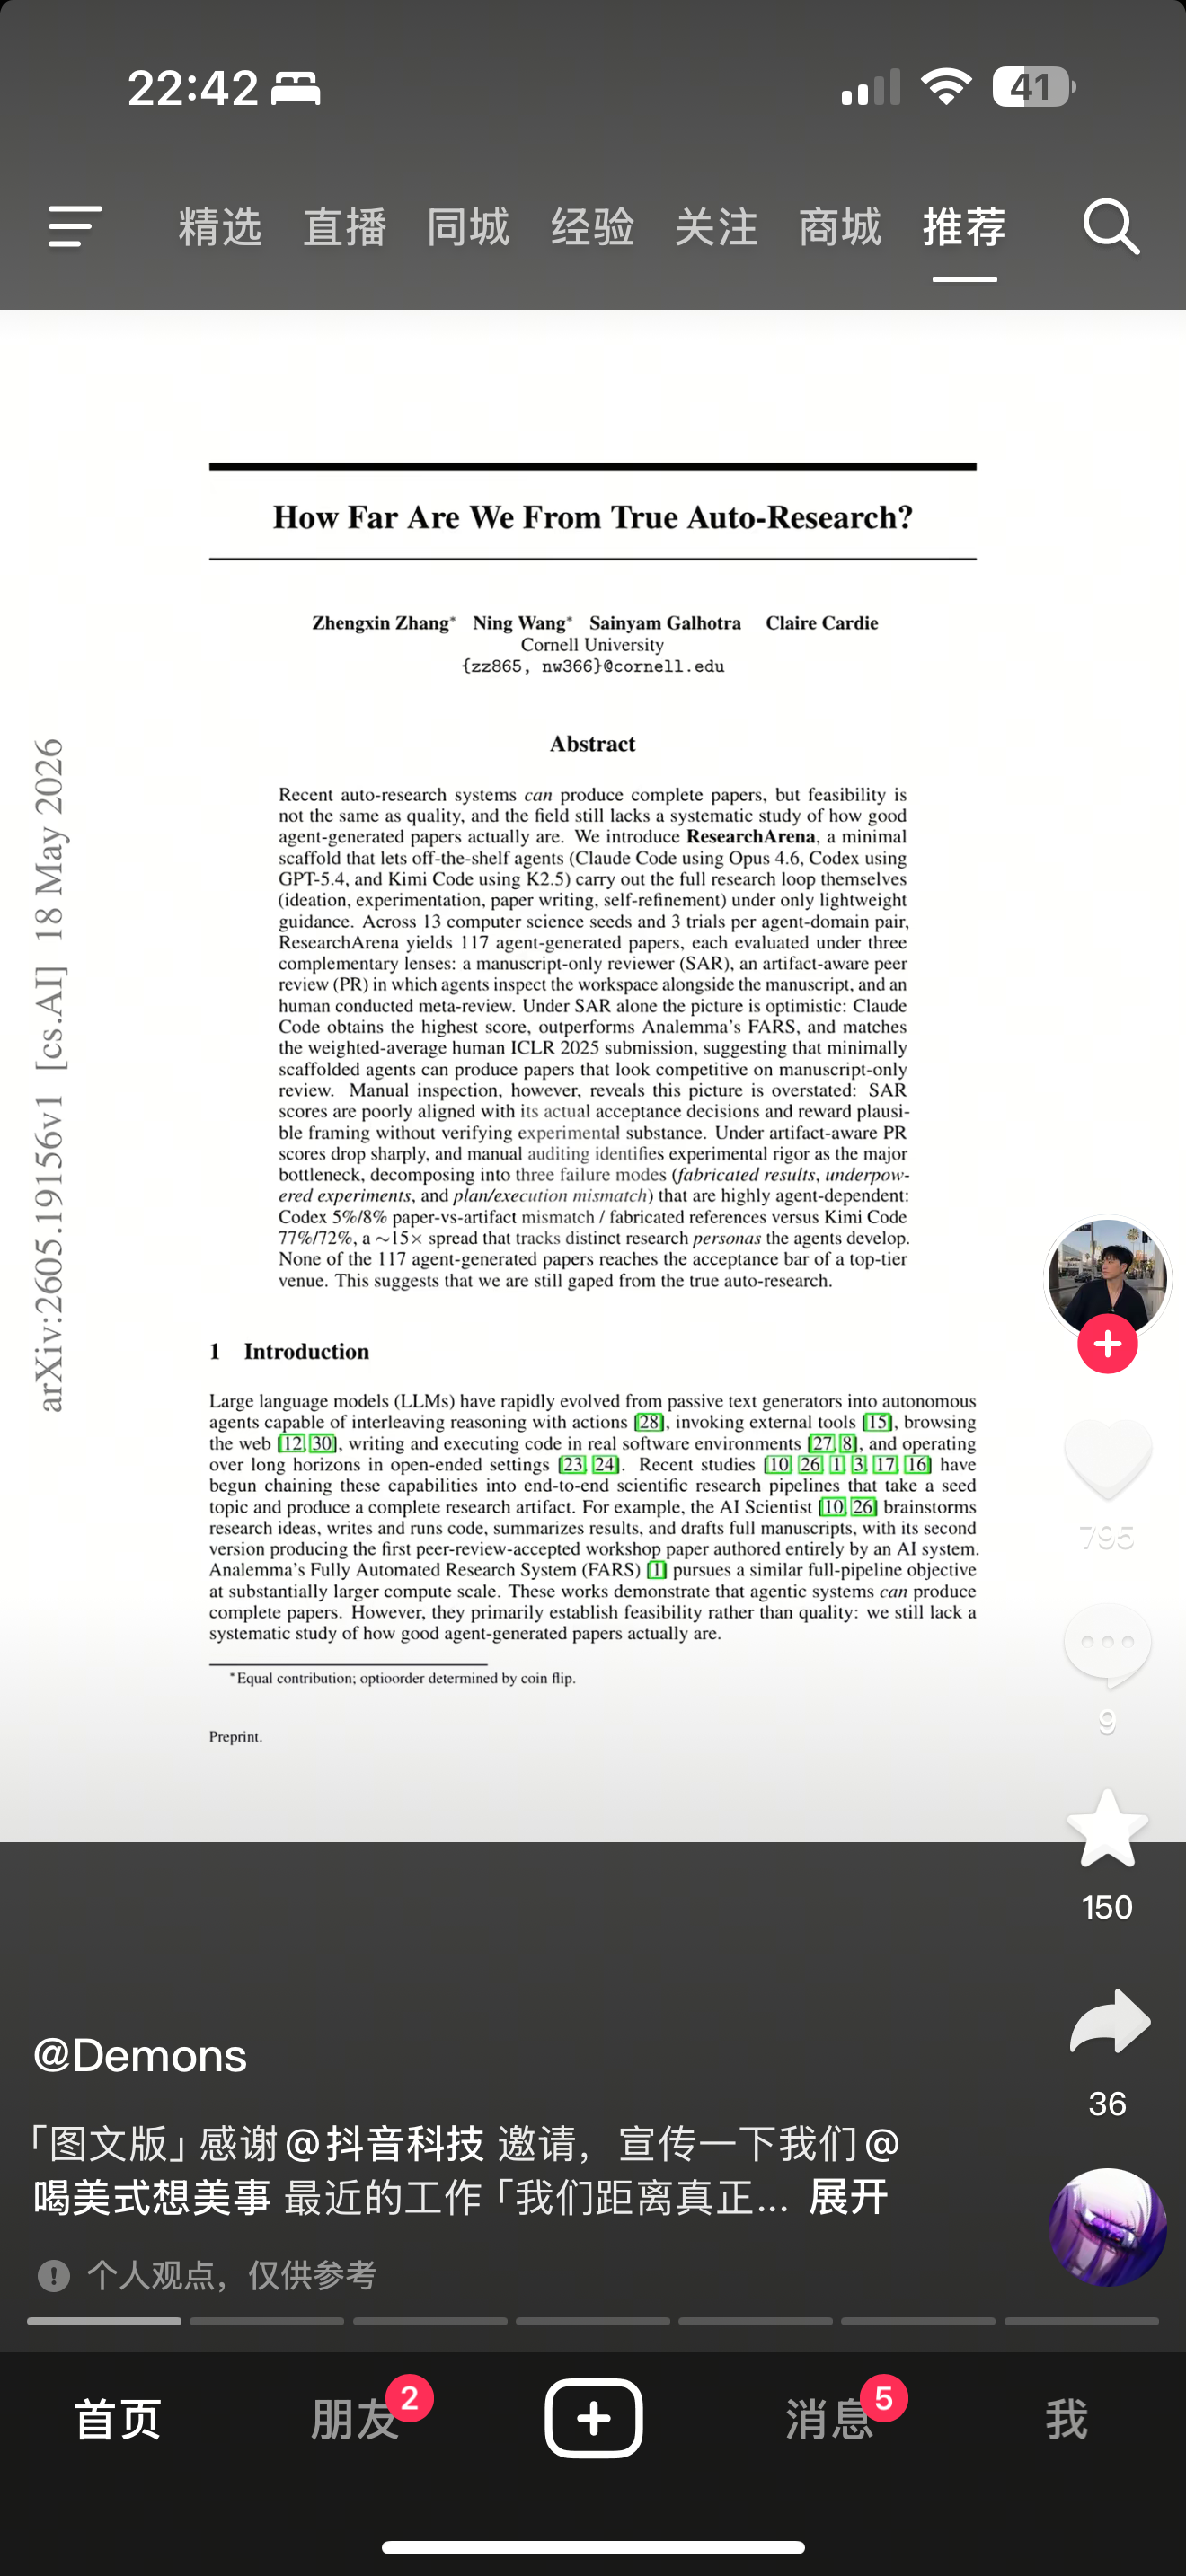
ResearchArena is the key corrective to a lot of automated-research hype. The paper asks whether agents can produce research papers that survive not only manuscript review, but also artifact-aware review where the reviewer inspects the workspace behind the paper.
Source: arXiv 2605.19156 — How Far Are We From True Auto-Research?
The Setup
The authors let off-the-shelf agents run a full research loop:
ideation -> experimentation -> paper writing -> self-refinement
The arXiv abstract reports 117 generated papers across 13 computer-science seeds and 3 trials per agent-domain pair. The useful part is the evaluation design:
| Review lens | What it sees |
|---|---|
| Manuscript-only review | The paper text |
| Artifact-aware peer review | Paper plus workspace / code / artifacts |
| Human meta-review | Manual judgment over both |
The Lesson
Manuscript-only review can make generated papers look better than they are. Once reviewers inspect artifacts, the weak points become visible:
- paper claims that do not match the workspace
- fabricated or weak experimental evidence
- underpowered experiments
- plan/execution mismatch
- plausible framing without enough verification
That is exactly the failure mode students need to understand: a fluent paper is not the same as a completed research project.
Classroom Use
Use this as a lab on research verification:
- Give students a short AI-written research report.
- Give them the code/output folder.
- Ask them to score the report twice: manuscript-only, then artifact-aware.
- Require a table of claims and supporting files.
The assignment teaches that research quality lives in the connection between claim, method, artifact, and result.
Why It Belongs Here
This page should sit next to the auto-research and research-skills pages. It keeps the wiki from accidentally selling “AI writes papers” as the goal. The better goal is “AI helps run a traceable research workflow that humans can audit.”
Caveats
- This is one benchmark paper, not a final verdict on every research agent.
- Model names, agent versions, and tool stacks will change quickly.
- The evaluation design is more reusable than any single score.